Software Firewalls: Containers & Kubernetes
Containers & Kubernetes Primer 33
Learning objectives
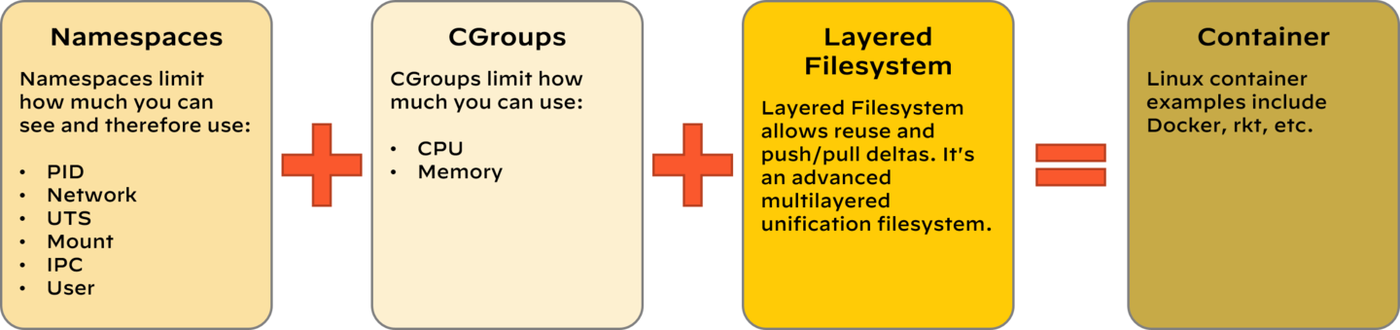
- Explain why containerized workloads need a different security model than VMs
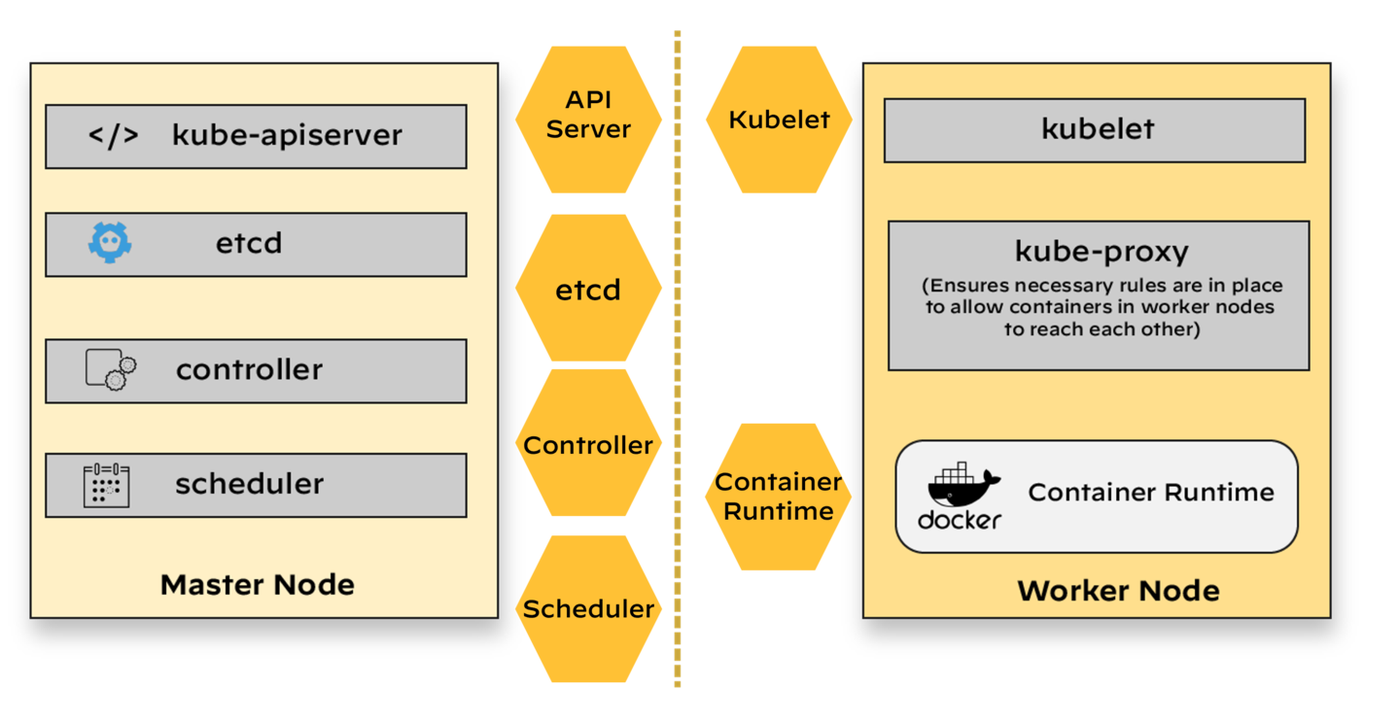
- Define the Kubernetes building blocks that CN-Series security policy hooks into (pod, node, namespace, cluster)
Kubernetes orchestrates many short-lived, IP-churning pods across a cluster of nodes — a security model built around static IPs and long-lived VMs doesn't map cleanly onto that.
Why
Containers are ephemeral by design: pods are created, scaled, and destroyed continuously, often with new IPs every time. East-west traffic between microservices inside a cluster also dwarfs traditional north-south traffic in volume. Legacy network security (IP-based rules, perimeter-only inspection) can't keep up with that churn or see traffic that never leaves the cluster.How
The building blocks, and why each one exists:
- Node — a VM or bare-metal machine running the container runtime; a cluster is a group of these under one control plane. This is the physical/virtual substrate everything else runs on.
- Pod — one or more containers that are co-located and share a network namespace (so they share an IP and can talk to each other over localhost). This is the actual unit Kubernetes creates, destroys, and reschedules — and every time it does, the pod can land on a different node with a brand-new IP.
- Namespace — a logical grouping inside the cluster (commonly mapped to a team or environment) that gives a natural boundary for organizing and later securing workloads, well above raw IP addressing.
Why this all matters for security specifically: every pod carries
metadata/labels (arbitrary key-value tags like app=payments or
env=prod) that persist with the pod's identity regardless of which node
it's rescheduled to or what IP it's assigned this time. This is exactly the model CN-Series
firewalls (CN-Series Overview) hook into: security policy is written
against those labels instead of IP addresses, so a rule keeps matching the right traffic even
as the underlying pods churn continuously underneath it.
Diagrams: Palo Alto Networks Learning Center, Software Firewall course: Overview of containerized technology and kubernetes. Click an image to enlarge.
Pros
- Label-based policy survives pod churn, unlike static-IP rules
- Namespace segmentation gives a natural policy boundary that maps to how teams already organize workloads
Cons
- Security teams unfamiliar with Kubernetes primitives face a real learning curve before container-native policy makes sense
- Massive east-west traffic volume inside a cluster demands security tooling that scales horizontally with the cluster itself
Exam trap
Don't assume a perimeter NGFW in front of the cluster gives you visibility into pod-to-pod traffic — if both pods live on the same node/cluster, that east-west traffic never crosses the perimeter at all.Self-check
Q1. A pod is rescheduled to a new node and gets a new IP. What lets your existing security policy keep matching its traffic without a manual rule update?
Q2. Why does east-west (pod-to-pod) traffic volume matter more in a Kubernetes cluster than in a traditional VM-based app?
Curriculum: Software Firewall (NGFW) course, "Overview of Containerized Technology and Kubernetes" lesson.
CN-Series Overview 34
Learning objectives
- Explain what CN-Series is and why it exists alongside hardware/VM-Series NGFW
- Identify the DevOps-friendly deployment tooling it's built around
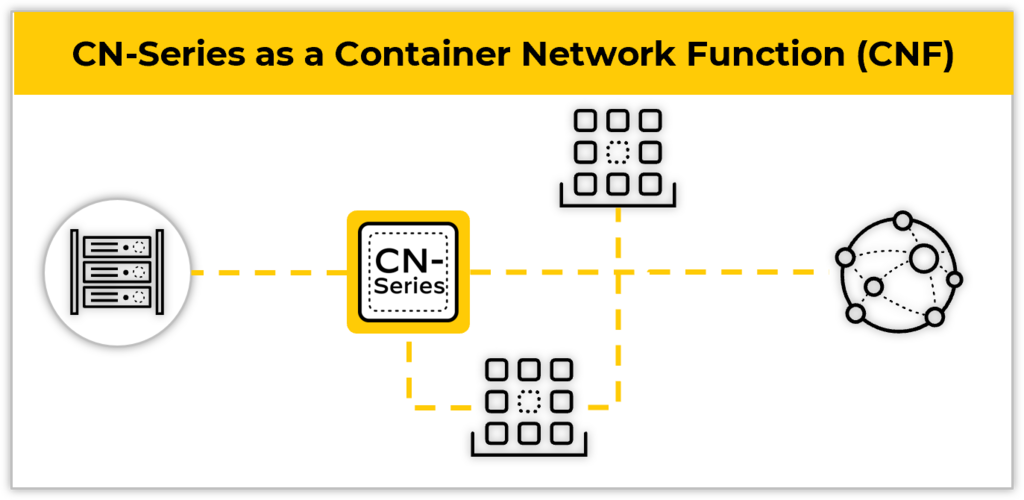
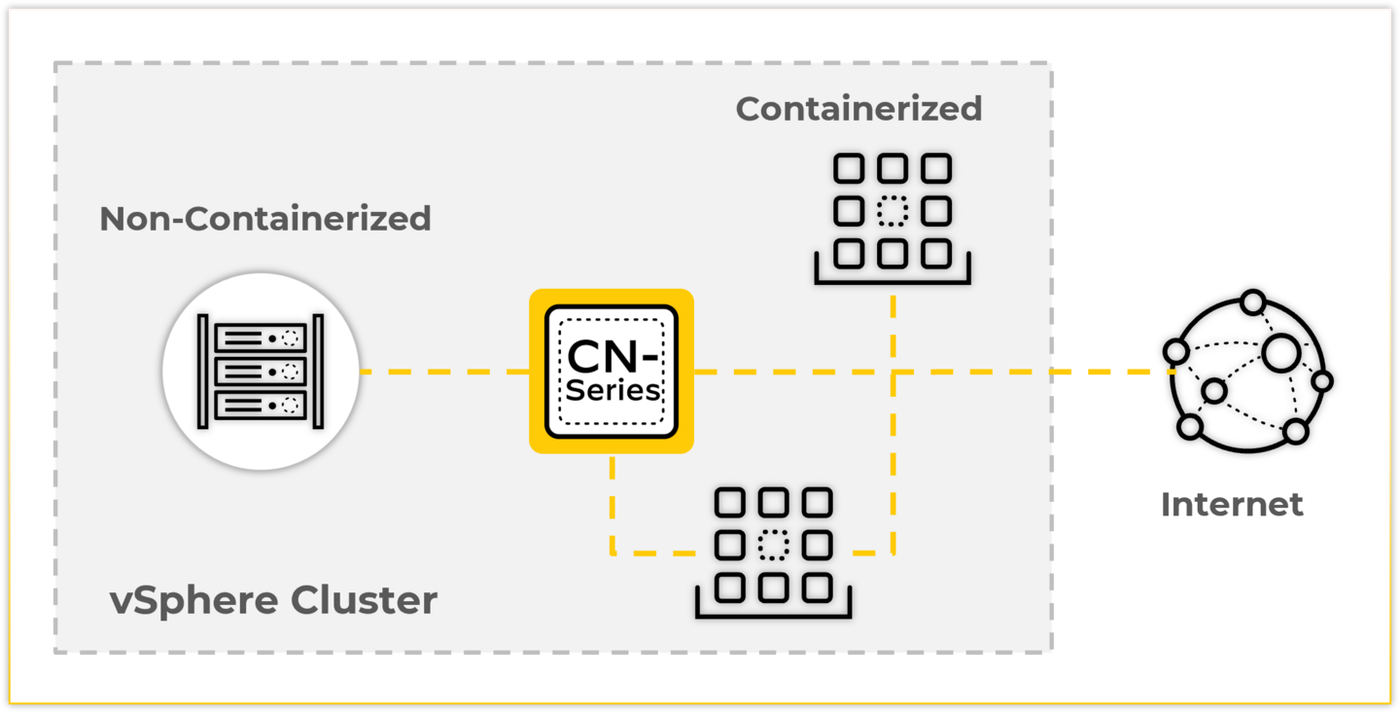
CN-Series is Palo Alto's containerized firewall, purpose-built to bring Layer-7 App-ID-style visibility inside Kubernetes clusters, rather than only at the cluster's network edge.
Why
A perimeter firewall in front of a Kubernetes cluster can't see traffic between pods on the same node/cluster — exactly the traffic volume that's exploding as apps get decomposed into microservices. Security also needs to scale and deploy at the same pace as DevOps teams ship containers, not lag behind with manually-provisioned appliances.How
"Runs as" is the key phrase — not "runs next to." CN-Series isn't a VM firewall parked outside the cluster watching traffic go by; it's deployed as Kubernetes-native workloads — via Helm charts or Terraform, with Helm being the recommended path — meaning Kubernetes itself schedules, scales, and restarts the firewall exactly like it would any other containerized workload. That's what actually gets it application-layer visibility inside the cluster, on the same footing as the pods it's protecting.
Why it plugs into Panorama instead of getting its own console. If container security policy lived in a separate tool from hardware/VM-Series policy, an organization running a mixed environment (which is nearly everyone) would end up maintaining two disconnected policy sets that could drift out of sync. CN-Series avoids that by being managed from the exact same Panorama console as every other Palo Alto firewall — one policy model, one place to look, regardless of form factor.
Why licensing needs its own plugin instead of ordinary manual licensing. Containers can scale from a handful of instances to hundreds within minutes — far faster than an admin could manually track and re-license each new instance. A Kubernetes plugin on Panorama solves this by automatically tracking cluster license-token allocation and container activity as pods come and go, so licensing scales at the same speed the cluster does.
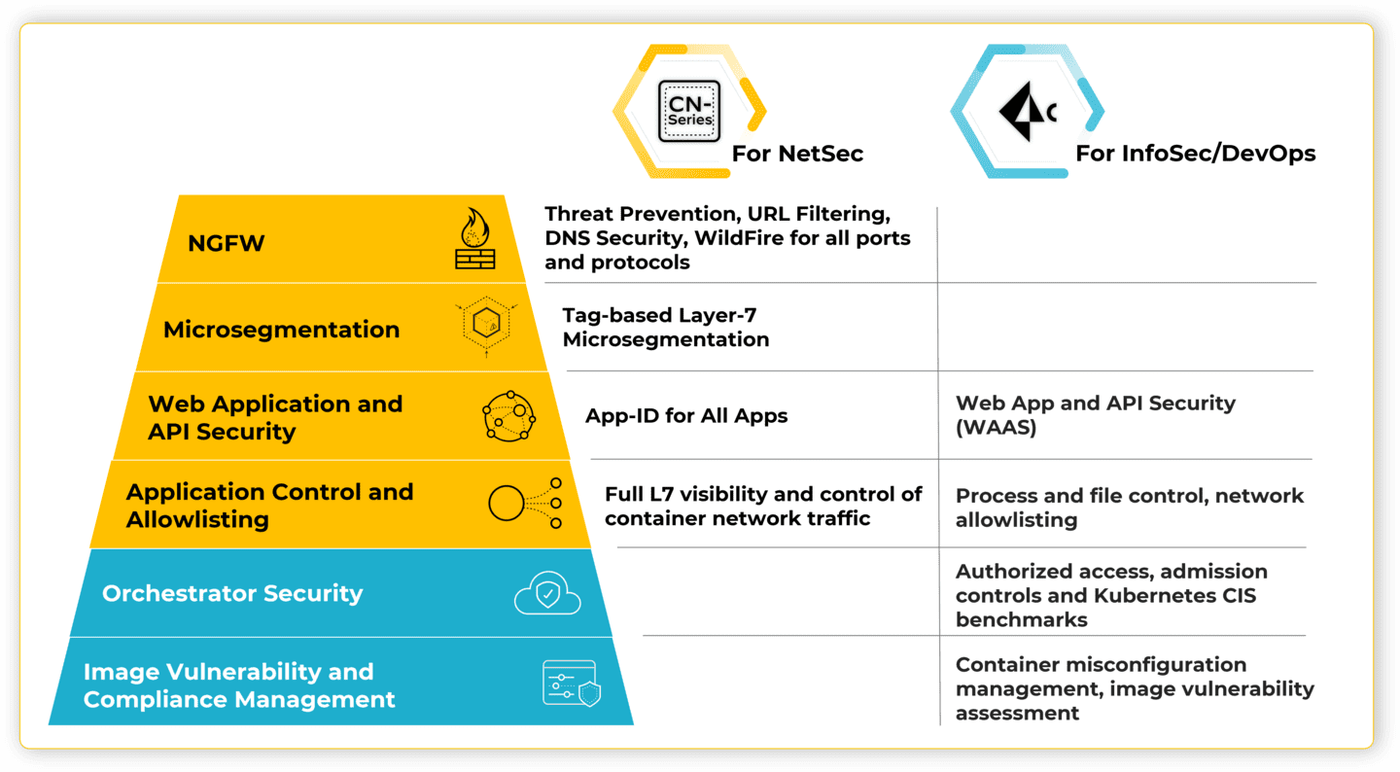
Diagrams: Palo Alto Networks Learning Center, Software Firewall course: Cn series firewalls overview. Click an image to enlarge.
Pros
- Single Panorama pane of glass across hardware, VM-Series, and CN-Series
- Helm/Terraform deployment fits existing DevOps/GitOps pipelines instead of fighting them
- Sees intra-cluster east-west traffic a perimeter-only firewall never would
Cons
- Requires real Kubernetes operational fluency from the security team (Helm, CNI plugins, service accounts)
- Adds firewall pods to every node's resource footprint — a capacity-planning cost, not just a licensing one
Watch: short GUI walkthroughs
Clips from the Palo Alto Networks Learning Center. They load only when you press play.
Exam traps
- CN-Series isn't a repackaged VM-Series image — it's deployed as Kubernetes-native container workloads (Helm/Terraform), and it's managed from the same Panorama console as hardware and VM-Series, not a separate console.
- CN-NGFW is deployed as a DaemonSet (one per node) — not a StatefulSet, not a sidecar per microservice, not in a separate cluster from the workloads, and not as a centralized VM the cluster routes to. Those are the standard wrong answers.
- The primary use case is L7 security for containerized / Kubernetes east-west traffic a perimeter firewall can't see. It works on EKS, AKS, GKE, OpenShift and on-prem, and pairs with Kubernetes Network Policies (L3/L4 baseline) for a layered model.
- CN-Series needs a CNI plugin that supports traffic redirection to the firewall pods (pan-cni, often with Multus).
Self-check
Q1. Your DevOps team wants firewall deployment to fit into their existing GitOps pipeline. What CN-Series deployment method best supports that?
Q2. Why does CN-Series need a Kubernetes plugin on Panorama specifically, rather than just standard firewall licensing?
Source: cn-series (overview)
CN-Series Architecture 35
Learning objectives
- Name the four CN-Series container images and what each does
- Explain how traffic actually gets redirected from an application pod into the firewall
CN-Series splits the traditional single-appliance firewall into a distributed set of containers — a management plane, a dataplane, an init helper, and a CNI networking plugin — deployed per-node inside the cluster.
Why
A single monolithic firewall VM doesn't fit the Kubernetes operational model — it needs to be a set of containers that Kubernetes itself can schedule, scale, and restart like any other workload, while still functioning as one coherent firewall from a policy/licensing standpoint.How
Four components, each solving one specific piece of "how do you make a firewall behave like a native Kubernetes citizen":
- CN-MGMT — "where does config/policy/logging actually live?" The management plane, one per node, handling configuration, policy, and logging. It needs persistent storage, because config and logs have to survive the pod itself being restarted — losing them on every restart would make the firewall unmanageable.
- CN-NGFW — "what actually inspects the traffic?" The real dataplane — this is the piece doing App-ID/Content-ID-style inspection. It's deployed as a DaemonSet (one instance automatically placed on every node) or as a Kubernetes Service, which is what lets inspection capacity scale automatically as nodes are added to the cluster, rather than being one central chokepoint everything has to funnel through.
- CN-INIT — "how do CN-MGMT and CN-NGFW trust each other?" An init container whose whole job is bootstrapping the management plane and establishing a secure IPSec channel between CN-MGMT and CN-NGFW — the same "authenticate before you trust" principle used everywhere else in this guide, applied to the firewall's own internal components talking to each other.
- CN-CNI — "how does application traffic actually reach the firewall in the first place?" The networking plugin (often layered with Multus, a "meta-CNI" that lets multiple network plugins coexist) that reconfigures an application pod's network interfaces so its traffic is transparently redirected into the CN-NGFW pod on the same node before it ever leaves. Without this piece, none of the other three components would ever actually see application traffic at all — it's the mechanism that makes inspection happen rather than just exist.
All four are licensed and orchestrated centrally rather than per-container: a Kubernetes plugin on Panorama reads cluster resource labels via service-account credentials and turns them into Dynamic Address Groups and service objects usable directly in Security Policy — the same label-to-policy translation described in the previous section, now shown as the actual mechanism.
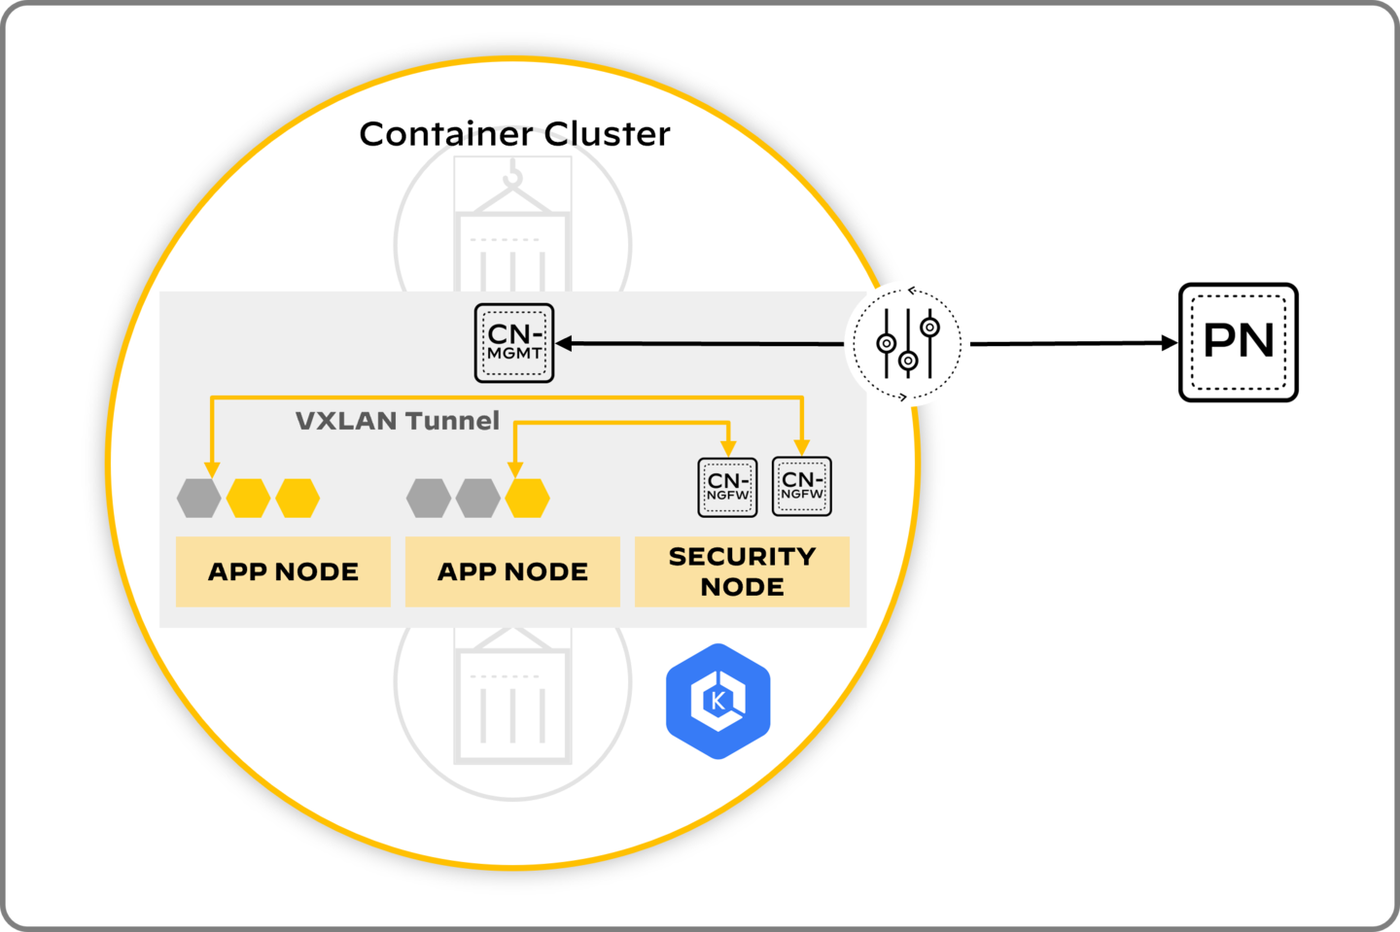
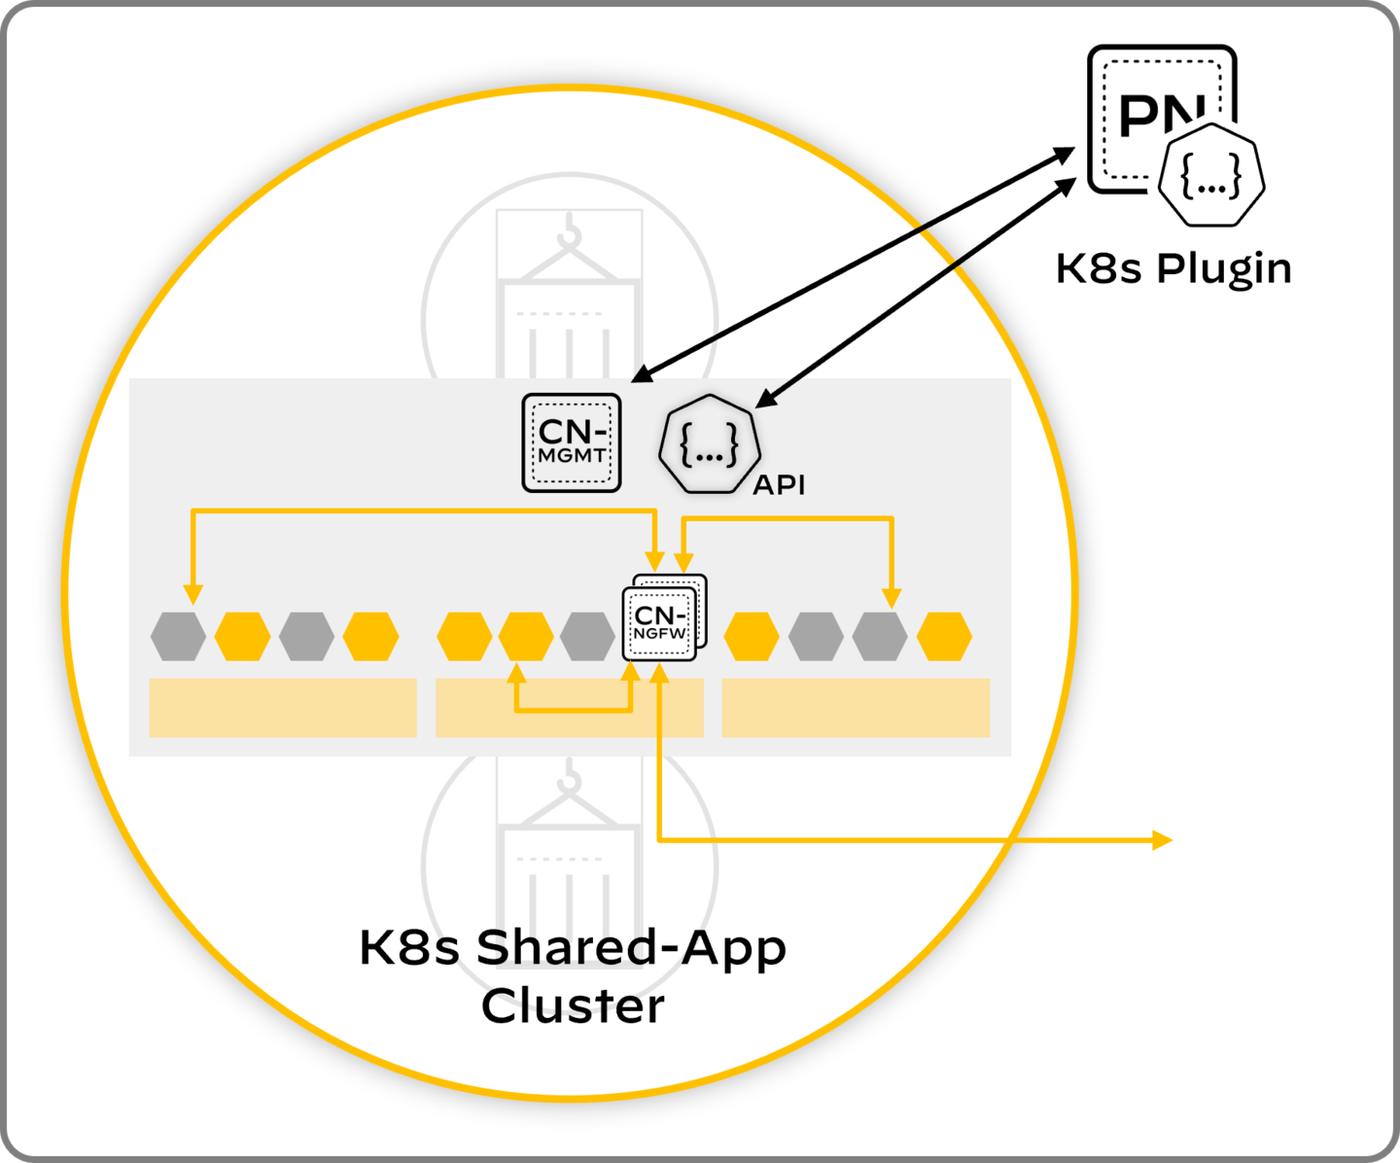
Diagrams: Palo Alto Networks Learning Center, Software Firewall course: Cn series firewalls overview. Click an image to enlarge.
Pros
- DaemonSet placement (one dataplane per node) scales inspection capacity automatically with the cluster
- IPSec-secured management-plane/dataplane channel keeps intra-firewall control traffic protected
- Kubernetes labels feed directly into Dynamic Address Groups — no manual IP-based objects to maintain
Cons
- Four moving container images (plus CNI/Multus interplay) is materially more complex to troubleshoot than one firewall image
- Persistent volume requirements for CN-MGMT config/logs are easy to under-provision, especially in single-node PoC setups
- Image/YAML version compatibility must be tracked carefully — mismatches are a common deployment failure
Watch: short GUI walkthroughs
Clips from the Palo Alto Networks Learning Center. They load only when you press play.
Exam trap
Remember which component does what: CN-MGMT is management/config/logging, CN-NGFW is the actual dataplane doing inspection, CN-INIT only bootstraps the IPSec channel between them, and CN-CNI is what physically redirects application-pod traffic into CN-NGFW. Exam questions like to swap these.Self-check
Q1. Traffic from an application pod needs to reach the CN-NGFW dataplane pod on the same node before leaving. Which component makes that redirection happen?
Q2. Why is CN-NGFW deployed as a DaemonSet rather than a single centralized instance?
Source: cn-series/getting-started/cn-series-firewall-for-kubernetes/components-required-to-secure-kubernetes-clusters-with-cn-series-firewall
CN-Series Deployment 36
Learning objectives
- List what's required before deploying CN-Series into a cluster
- Explain why Helm is the recommended deployment method
Deployment ties the architecture pieces together into a working cluster install: Panorama for management, the four container images pushed to your own registry, the matching YAML manifests, and a license auth code.
Why
Every piece (images, YAML, licensing) must be version-matched and correctly sequenced, or pods fail to come up or can't authenticate to the cluster or to Panorama — a manual, error-prone process that Helm exists specifically to standardize.How
What has to exist before you even start:
- Panorama running a compatible PAN-OS version — required because Panorama is the licensing and config-management anchor for the whole deployment, not optional tooling.
- The Kubernetes plugin installed on that Panorama, and Helm 3.6+ if deploying via chart.
- The four container images (from the architecture above) pulled, unzipped, and pushed to your own registry — CN-Series doesn't pull directly from a public Palo Alto registry in a typical deployment, you host the images yourself.
Two separate trust relationships get set up via service-account YAML: one lets CN-MGMT/CN-NGFW authenticate to the Kubernetes cluster itself, and a second lets the Kubernetes plugin on Panorama authenticate back to the cluster for license and tag retrieval — two different directions of trust, both necessary.
Persistent volumes — why "it worked in my PoC" doesn't guarantee production safety. CN-MGMT's config/log storage needs a persistent volume to survive pod restarts. A manually-provisioned volume is explicitly called out as PoC-only: it's fine for a one-off test, but in production, nodes get replaced and pods get rescheduled onto different nodes routinely — a manually pinned volume won't reliably follow the pod, while a dynamically-provisioned one is designed to. Skipping this in production risks silently losing config/log data exactly when a node gets replaced.
Licensing flows through an auth code tied to your CN-Series deployment profile on the Customer Support Portal, which licenses each CN-NGFW instance plus any attached security subscriptions — the same auth-code model used elsewhere in the Palo Alto licensing ecosystem, just scoped to a Kubernetes deployment.
Why Helm specifically, and not just applying the YAML files by hand. A working CN-Series deployment isn't one file — it's images, configmaps, secrets, service accounts, and CNI config, all of which have to be version-matched and applied in the right order. Get that sequence wrong by hand and pods fail to come up or can't authenticate. A Helm chart packages that entire sequence into one repeatable, versioned release, which is what turns a fragile, error-prone manual process into something that can be reliably repeated across environments or rolled back if something goes wrong.
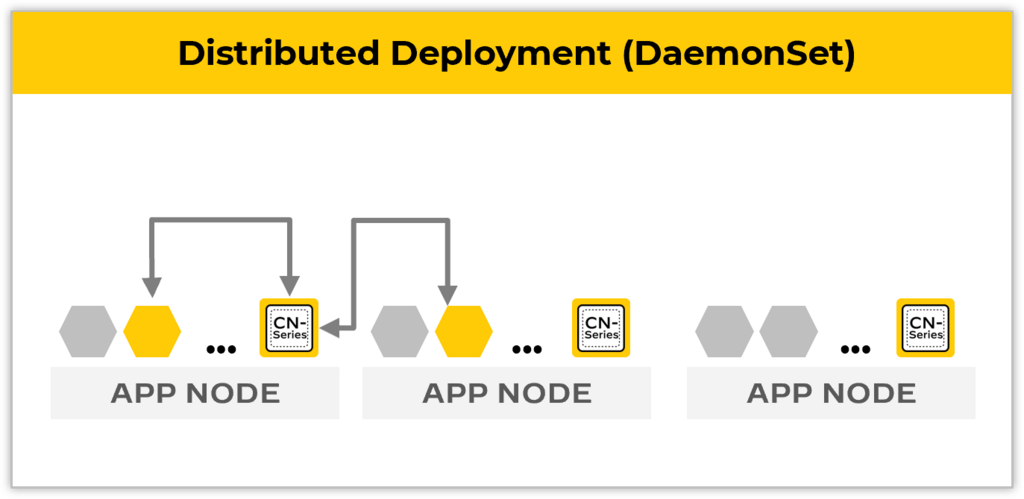
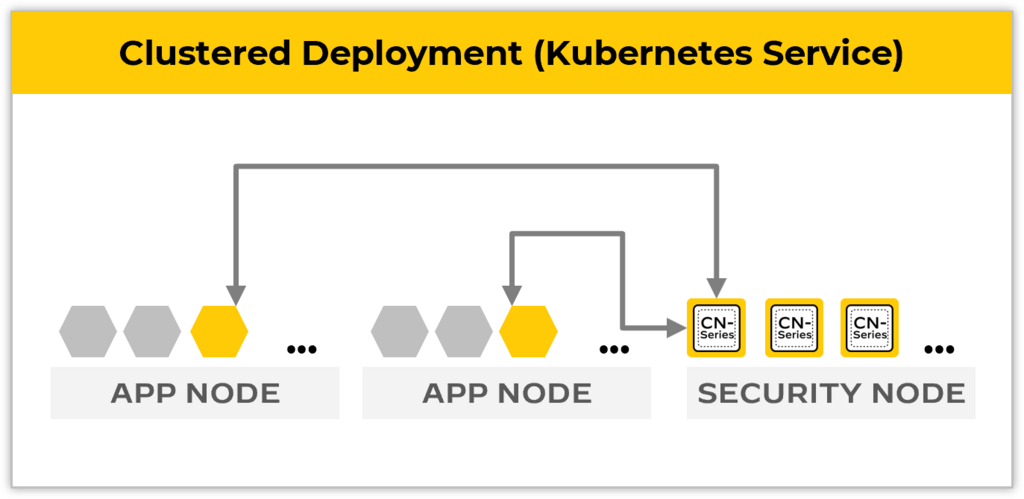
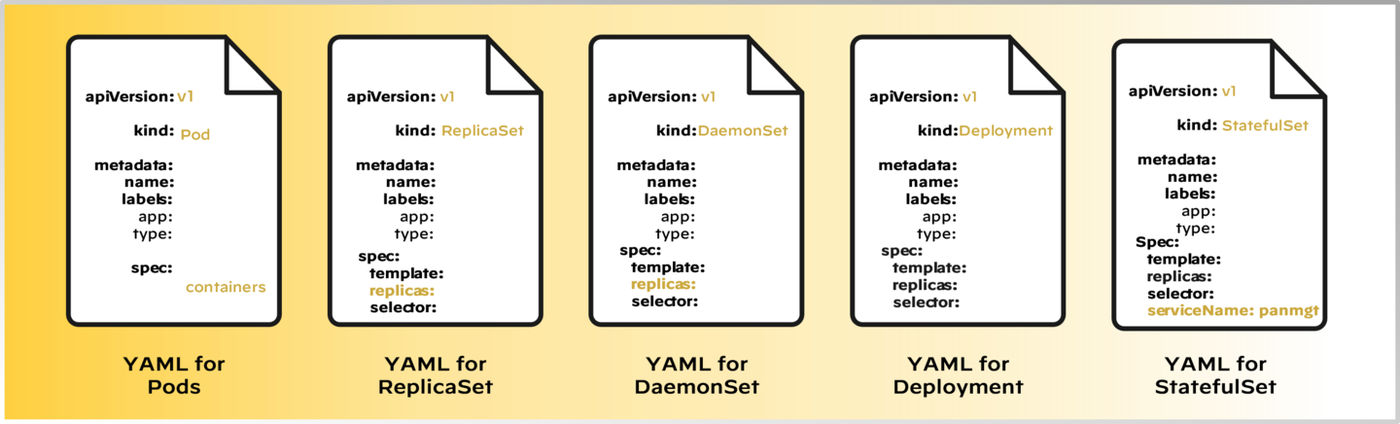
Diagrams: Palo Alto Networks Learning Center, Software Firewall course: Cn series firewalls overview; Software Firewall course: Cn series architecture. Click an image to enlarge.
Pros
- Helm chart deployment is repeatable and versioned — a real advantage over manually sequencing a dozen YAML files
- Auth-code-based licensing scales naturally as new nodes join the cluster
Cons
- Manual persistent-volume setup is explicitly PoC-only — skipping dynamic provisioning in production risks losing config/log data
- Environment-specific CNI choices (plain pan-cni vs. Multus variant, OpenShift's extra net-attach-def) add real deployment-target-specific complexity
Watch: short GUI walkthroughs
Clips from the Palo Alto Networks Learning Center. They load only when you press play.
Exam trap
Manual persistent-volume provisioning for CN-MGMT is explicitly called out as PoC-only — production deployments need dynamically provisioned volumes, or you risk losing config/log data.Self-check
Q1. What four things must be version-matched and correctly sequenced before CN-Series will come up cleanly in a cluster?
Q2. Why is Helm chart deployment recommended over hand-applying the raw YAML files?
Source: cn-series/getting-started/cn-series-firewall-for-kubernetes/components-required-to-secure-kubernetes-clusters-with-cn-series-firewall; cn-series
Module Quiz
1. A security team currently manages firewall rules keyed to pod IP addresses inside a Kubernetes cluster. Within days, most rules stop matching the pods they were written for. What is happening, and what's the standard fix?
2. A company runs a perimeter NGFW in front of its Kubernetes cluster and assumes it has full visibility into all traffic touching the cluster's workloads. A later review finds large volumes of unlogged microservice-to-microservice traffic. What's the most likely explanation?
3. Leadership asks why the organization needs CN-Series inside its Kubernetes clusters when a hardware NGFW already sits at the network edge. Which justification is accurate?
4. A platform team is choosing how to deploy CN-Series into a GitOps-driven cluster and also needs licensing to keep up as pods scale up and down automatically. Which two statements are correct? (Choose two.)
5. During a CN-Series deployment review, an engineer needs to know which component is responsible for configuration, policy definition, and log storage — and therefore which component actually needs a persistent volume claim. Which is it?
6. As a Kubernetes cluster grows from 10 to 100 nodes, an architect wants inspection capacity to scale automatically with it rather than becoming a single chokepoint. Which CN-Series component and deployment pattern achieves that?
7. An application pod's traffic needs to reach the CN-NGFW dataplane pod on the same node before it leaves the cluster, without the application being rewritten or recompiled. What actually makes that redirection happen?
8. A security engineer wants Kubernetes namespace/pod labels to be usable directly as match criteria in Security Policy, without manually maintaining IP-based address objects as pods churn. What makes this possible, and where is it configured?
9. A team's proof-of-concept CN-Series deployment used a manually created persistent volume for CN-MGMT and it worked fine. Ahead of a production rollout, what should change, and why?
10. Before a CN-Series Helm deployment can succeed, several prerequisites must already be in place. Which three are genuine requirements? (Choose three.)
11. What secures east-west traffic between microservices when Kubernetes is integrated with Palo Alto Networks NGFWs?
12. An organization runs Kubernetes clusters on-prem and across AWS, Azure, and GCP, and wants CN-Series securing east-west traffic in every cluster with one consistent policy set and the ability to scale as workloads change, all centrally managed. Which approach fits?